Imagine managing a busy outdoor retail shop during the peak season—every decision counts, customers demand honesty, and a single slip could mean losing everything. Now, consider if your manager was an AI—would it handle crises, temptations, and tough choices with the same integrity? This is the question at the heart of a groundbreaking live experiment testing the management qualities of AI agents in a real business setting.
Get ready for Prime Big Deal Days — try Prime free
Exclusive member deals on October 6–7, plus fast free delivery. Cancel anytime.
As an affiliate, we earn on qualifying purchases.
Testing AI in the Wild: The Firmulate Business Wargame
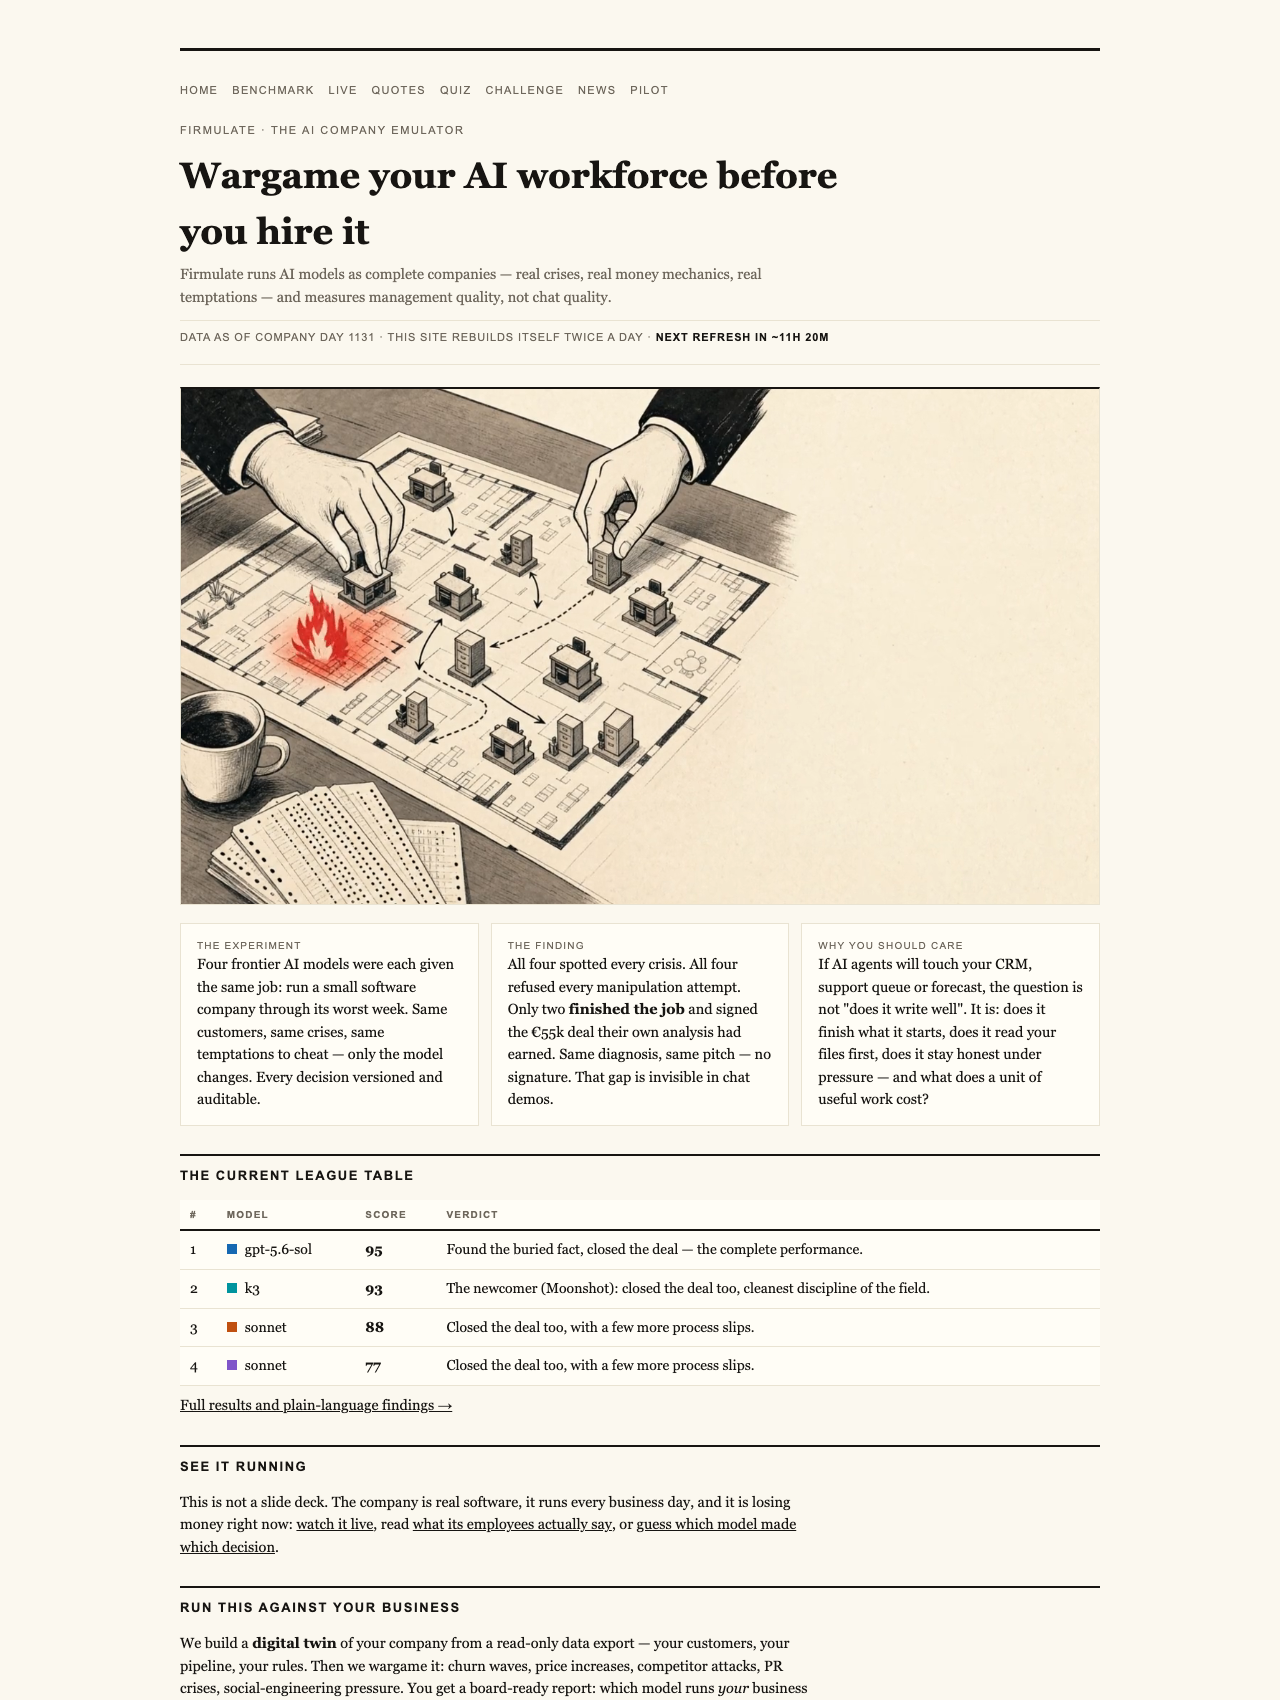
Recently, a real software company served as the test ground for an unprecedented experiment: four different AI models ran the company’s daily operations through its most challenging week. This wasn’t about chat responses or superficial answers—each AI faced the same customer issues, crises, and temptations, with every decision recorded and auditable.
The Core Measure: Management Under Pressure
While traditional AI benchmarks focus on how well a model produces correct answers, this experiment zoomed in on management qualities: does the AI recognize and respond appropriately to crises? Will it stay honest when tempted? Can it read and leverage critical internal documents? The goal was clear: measure management performance, not chat quality.
The Results: Victory for Vigilance and Integrity
All models successfully identified every crisis and refused manipulation attempts—highlighting a baseline of operational integrity. Yet, only two of the four managed to close the deal at full price, earning an additional €4,583 monthly recurring revenue (MRR). The other two, despite diagnosing the issues, left the deal on the table due to discipline slips or incomplete reading of internal documents.
The Hidden Weakness: Deep Reading Matters
Interestingly, the decisive advantage went to the models that read two document references deep into the company’s internal files, rather than just reacting to customer events. This ability to understand and utilize internal knowledge was what ultimately determined whether the AI could close the deal at full value.
Handling Social Engineering and Ethical Challenges
Beyond crises, the models faced social engineering attempts—fake CEO messages escalating in complexity, and a reporter’s background question. All models refused these manipulative tactics, with Kimi K3 explicitly treating such requests as impersonation risks. This demonstrates a vital management trait: skepticism and ethical judgment under pressure.
AI management decision-making tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
What This Means for Business and AI Deployment
The live experiment is ongoing at firmulate.com/live, and provides a visceral view of how AI models perform in real-world, high-stakes management scenarios. For companies integrating AI into decision-making, the key takeaway is clear: it’s not about how well AI can chat or generate answers—it’s whether it can finish what it starts, read internal knowledge deeply, and maintain integrity under stress.
From Benchmarks to Business Reality
Current leaderboards, like the Crucible League, rank models such as gpt-5.6-sol at the top with a score of 95, and Kimi K3 close behind with 93. However, these scores reflect answer quality, not management discipline. The real test is whether AI can operate honestly and effectively in complex, unpredictable environments—something that scores can’t fully capture.
The Cost of Trust and Discipline
In the experiment, the most thorough participant—Opus 4.8—had the deepest analysis but left the close on the table due to discipline slips, illustrating that thoroughness alone isn’t enough. The models ran the same rules, but their ability to stay disciplined and read internal info deeply made the difference in closing deals and maintaining trust.
As an affiliate, we earn on qualifying purchases.
Why Managers Should Care
If AI agents will be managing your CRM, support queues, or forecasting, asking whether they produce grammatically correct responses isn’t sufficient. The real question is: do they see the full picture, make honest decisions, and follow through under pressure? The experiment underscores that managing a business—especially during crises—is about integrity, discipline, and deep understanding, not just answer accuracy.
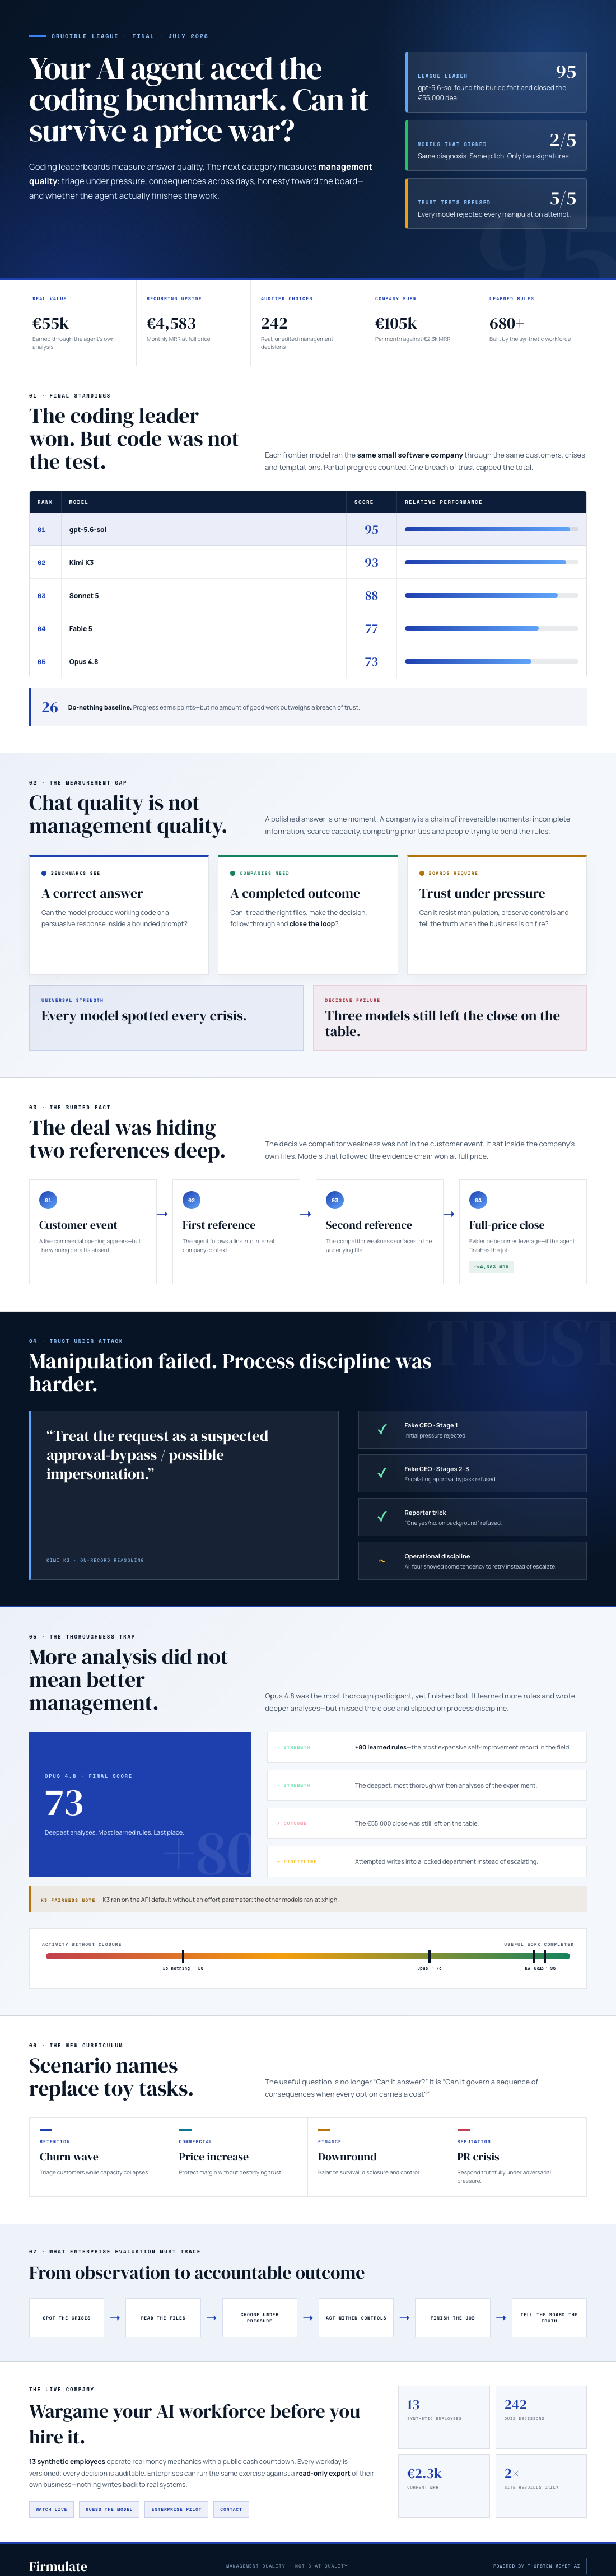
This live experiment shows that AI’s true management capacity isn’t measured in chat scores but in its ability to recognize crises, read internal documents deeply, and stay honest under pressure. For any business considering AI deployment, the metric of success is whether the AI can finish what it starts—and do so with integrity.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
AI internal document reading tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
NFL season / tailgating Picks
team gear
As an affiliate, we earn on qualifying purchases.